This article introduces the Integrated Sociotechnical Exposure Framework (ISEF) to assess generative AI exposure in civil and environmental engineering by separating technical AI suitability (TA) from institutional resistance (IR). The contribution is an operational measurement framework, not a claim that institutional constraint is a new concept.
The framework is applied to 674 O*NET tasks across 28 occupations. Task-variable pairs are scored by three large language models under a fixed rubric and then aggregated to occupation level. Exposure is modelled with a multiplicative form, and sensitivity checks compare additive, min-rule, and geometric alternatives. A small external practitioner survey is used as a calibration check rather than as task-level validation.
A large group of occupations score well on technical AI suitability but stay heavily constrained by liability, compliance, and sign-off requirements. The cleaned practitioner survey points in the same direction: across 15 task vignettes, higher perceived institutional constraint is strongly associated with lower adjusted AI exposure.
The scoring still leans on LLMs, and the practitioner sample is small. Because no same-task expert panel is available in the present revision, the results should be read as a transparent first-stage index. The nine-response practitioner exercise is preliminary calibration, not validation of the occupation-level index or its constructed adjusted-score analogue. The natural next step is a larger same-task expert panel paired with adoption-linked field evidence.
For engineering organisations, adoption strategy is better anchored in accountable workflows, auditability, and professional review processes than in model capability on its own.
The paper pulls governance constraints into the exposure measure itself, and uses that lens to explain why technical-only indices tend to overstate near-term generative AI uptake in regulated engineering work. Its measurement logic is potentially transferable to other regulated professions, but any such application requires domain-specific specification and calibration of the institutional-resistance construct.
Introduction
Civil and environmental engineering is a good place to take the phrase “AI exposure” seriously. Generative systems can now draft reports, produce code, and assist analytical work at a level that would have looked implausible only a few years ago (OpenAI, 2023; Bubeck et al., 2023). Engineering decisions still pass through licensure, liability, and review chains that were built long before these tools existed. Whether AI can produce a particular output, and whether that output can enter an accountable workflow, are two different questions; much of the current confusion around generative AI in engineering comes from treating them as one.
The exposure literature has built strong instruments for the first question. Task-content measures identified codifiable work, routine procedures, and pattern-based activity as the natural unit of analysis (Autor, 2015; Frey & Osborne, 2017). That foundation remains useful for regulated engineering, but it is incomplete. A task may read as technically suitable for AI assistance and still sit inside a sign-off, audit, or liability structure that keeps AI-generated outputs out of the accountable record (Jasanoff, 2016).
This paper develops the Integrated Sociotechnical Exposure Framework (ISEF) in response. ISEF is a task-level framework for civil and environmental engineering that scores technical AI suitability and institutional resistance through the same rubric-based protocol, so neither side gets reduced to background. Its novelty is practical and methodological: it turns a familiar sociotechnical insight into a reproducible occupation-level measurement design.
Research questions. Three questions guide the analysis:
How can technical AI suitability and institutional resistance be operationalised separately for civil and environmental engineering tasks?
How do occupation-level exposure patterns change when institutional resistance is incorporated into technical exposure measurement?
How sensitive are the resulting rankings and groupings to modelling choices, including functional form and clustering assumptions?
The multiplicative form developed below treats mandatory sign-off and similar requirements as binding limits on workable exposure, not as small adjustments at the margin. The analysis covers 28 engineering occupations and 674 O*NET task statements (Peterson et al., 2001). Throughout, exposure is used as a descriptive indicator of where technical suitability meets institutional permission, and it is kept separate from claims about adoption timing or labour displacement.
Literature review
This section positions the framework in four bodies of work: task-based exposure measurement, professional regulation, sociotechnical governance, and digital transformation in engineering workflows. The review is not used to claim that institutions have been ignored in prior scholarship. The point is narrower: existing literatures explain why adoption is institutionally mediated, while the present paper turns that insight into an occupation-level measurement protocol.
Task-based AI exposure measurement
Task-based exposure measures have a long lineage in labour economics. The early generation linked routine task content to substitution risk and set the analytical template later work would extend (Autor, 2015; Frey & Osborne, 2017). Labour-market studies then connected task displacement to job polarisation and wage inequality, while also showing why occupation-level averages can hide task-level variation (Goos, Manning, & Salomons, 2014; Arntz, Gregory, & Zierahn, 2017; Acemoglu & Restrepo, 2022). Subsequent studies narrowed the frame further, moving from whole occupations to the specific capabilities a machine-learning system can perform (Brynjolfsson, Mitchell, & Rock, 2018; Webb, 2020). Reviews of AI, labour, and productivity also stress that exposure measures need to be separated from realised firm-level adoption (Raj & Seamans, 2019). Generative AI has revived that agenda: recent indices ask whether language models can perform or assist with occupational tasks (Eloundou, Manning, Mishkin, & Rock, 2023; Felten, Raj, & Seamans, 2021; Tolan et al., 2021), while experimental and field evidence shows that gains are task-contingent rather than uniform (Noy & Zhang, 2023; Dell’Acqua et al., 2023). These measures handle technical fit competently, but they remain thinner on the institutional side of adoption, which is the part of the problem this paper focuses on.
ISEF keeps task-level measurement but separates two dimensions that exposure scores typically fold together. Technical AI suitability (TA) asks whether generative AI can plausibly support the task. Institutional resistance (IR) asks whether responsibility, compliance duties, data governance, or organisational accountability make practical use harder. In engineering, the second question often matters as much as the first: a useful draft or calculation still has to clear review before it becomes actionable evidence.
Professional regulation and sociotechnical governance
Institutional accounts help explain why technical fit alone tends to undersell adoption frictions. Abbott (1988) argues that professional jurisdictions are sustained through expertise, credentialing, and control over what counts as legitimate practice; Freidson (2001) reads that control as a durable institutional logic, not a transitional friction. The implication for digital tools is sharper in Susskind and Susskind (2015): technology can redistribute the tasks professionals carry out without redistributing authority, sign-off, or liability. STS and organisational scholarship add the safety-critical angle. Jasanoff (2004) treats science and technology as co-produced with social order, and Jasanoff (2016) extends the argument to how risk technologies become acceptable—through standards, review procedures, and accountability arrangements, alongside any efficiency case. Sociomaterial and algorithmic-work research makes the same point at organisational scale: digital systems alter work through routines, documentation, and control relations rather than through technical capability alone (Leonardi, 2012; Kellogg, Valentine, & Christin, 2020).
Civil and environmental engineering sits at the sharp end of this argument because outputs are tied to public safety, environmental compliance, procurement rules, and professional sign-off. AI can help with drafting, checking, simulation support, and documentation, but the institutional layer still decides how those outputs are reviewed, recorded, and accepted. AI governance scholarship is useful here because it treats accountability, transparency, risk classification, and auditability as design conditions rather than optional afterthoughts (Calo, 2017; Floridi & Cowls, 2019; Raji et al., 2020; Veale & Borgesius, 2021; Weidinger et al., 2022). ISEF scores this institutional layer at task level using the same rubric-based logic applied to technical suitability, so the two sides of the problem stay comparable.
Generative AI in engineering workflows
Engineering research has tracked the spread of BIM, digital twins, machine learning, reservoir modelling, and other data-driven tools in infrastructure and subsurface work (Bock, 2015; Sacks, Eastman, Lee, & Teicholz, 2018; Mohaghegh, 2017; Azimi, Eslamlou, & Pekcan, 2020). Generative AI adds a particular complication on top of this trajectory: outputs can read as competent while remaining hard to verify, attribute, or certify. Foundation-model and generative-AI reviews make this verification problem especially salient because general-purpose models can be repurposed across domains faster than institutional controls can be standardised (Bommasani et al., 2021; Dwivedi et al., 2023). That gap carries weight when a flawed design note, permit draft, or environmental assessment has legal and safety consequences.
This distinction matters for Digital Transformation and Society because generative AI is not simply another productivity tool inserted into an existing workflow. In regulated engineering, model outputs become useful only when they can be documented, checked, attributed, insured, and signed off. A measurement framework that scores technical suitability without also scoring those governance conditions will tend to overstate the near-term exposure of safety-critical professional work.
Positioning of the present study
Exposure is therefore treated here as a sociotechnical construct: a description of where task suitability and institutional constraint meet, rather than a forecast of job loss or a snapshot of current firm-level uptake. The originality of ISEF lies in operationalisation. It combines a task-level rubric, a multi-model scoring protocol, and a gating specification that can be recalculated by other researchers. The empirical contribution remains descriptive, and the LLM-based scores should be read as a first-stage measurement exercise—one that can be inspected, challenged, and extended with stronger practitioner validation.
Methods
Sample and data
The study examines 28 civil and environmental engineering occupations from the O*NET database (version 28.0) (Peterson et al., 2001). The final sample consists of 674 unique tasks across managers, engineers, technologists/technicians, and related professionals. Table 1 provides an overview of the sample structure.
Measurement protocol
Technical and institutional factors are evaluated using the Generative AI Impact Index (GAII), which consists of 12 variables (seven TA; five IR). Table 2 provides a quick reference, while the full definitions and rubric are available in Supplementary Material B. The rubric is written out in full so that scoring decisions can be checked line by line.
The variable list was built through an iterative review of three sources: task-based AI exposure studies, sociotechnical and professional-regulation concepts, and civil engineering workflow characteristics. The TA variables capture recurring forms of task suitability in prior exposure measures, including data analysis, structured procedures, digital integration, and augmentation potential. The IR variables capture barriers repeatedly identified in professional and safety-critical domains, including legal responsibility, privacy, organisational trust, and sectoral gatekeeping. The list is not claimed to be exhaustive; it is a parsimonious operationalisation designed for transparent scoring and future recalibration. Domain Expertise is treated consistently as a TA variable because specialised knowledge can make a task more amenable to AI-assisted retrieval, drafting, or checking when appropriate expert oversight remains in place. Institutional accountability for that expert judgement is captured separately by Compliance/Responsibility and related IR variables.
The analysis measures exposure: the joint degree to which tasks are technically suitable and institutionally permissible. It does not forecast replacement or job loss.
The task–variable mapping protocol is set out in Supplementary Material A. The complete measurement protocol, defined in Supplementary Material B, documents every scoring rule used in the analysis. For each task, the initial mapping was conducted with a focus on the specific context of civil engineering. This conservative protocol involved reading task descriptions and identifying relevant variables supported by the text. The mapping was checked for internal consistency before model scoring, but it should not be confused with independent task-level expert validation. Supporting diagnostic tables and figures are provided in Supplementary Material C.
Scoring protocol
Task-variable pairs were evaluated using three large language model systems under fixed settings and a prompt template: ChatGPT-5, DeepSeek-R1, and Qwen-3. The same prompt, rubric, and aggregation code can be rerun by other researchers without proprietary tuning.
Design considerations for the scoring process included:
Three independent evaluation runs per model to mitigate session effects.
A single prompt template requiring a 0–10 score with a brief justification tied to the task text.
No post-hoc cleaning of outliers to maintain a realistic assessment of variance.
Clearing of session history between runs to ensure independent measurements.
Consistency was monitored across runs and stayed within the limits acceptable for a descriptive measurement exercise. Inter-model agreement is useful but cannot stand in for external validity. The three systems likely share training data, alignment pressures, and shared assumptions about professional work, so their consensus is treated here as a scalable first-stage signal rather than a substitute for domain-expert scoring. In response to reviewer concerns about circularity, a small practitioner survey was added during the revision period to check whether the TA/IR split survives outside the model-scoring loop; respondents rated 15 task vignettes from the questionnaire on AI assistance potential and institutional constraints. This survey is reported as calibration evidence only. It does not estimate expert–LLM agreement on the same tasks, and the manuscript therefore avoids presenting LLM consensus as independent validation.
Aggregation and analysis
The aggregation of task-level evaluations into occupation-level indices follows a structured procedure:
Stage 1: Consensus Scores. A mean is computed across all systems and runs for each task-variable pair (Equation 1):
where is the score for task and variable from system and run , with systems and runs per system.
Stage 2: Variable Aggregation. Evaluations are aggregated to the variable level using O*NET importance weights (Equation 2):
where is the normalised importance weight for task in occupation , with .
Stage 3: Index Construction. TA and IR are computed as unweighted means of their constituent variables and rescaled to a 0–100 range (Equation 3):
Exposure is then calculated through the multiplicative specification (Equation 4), incorporating the institutional context:
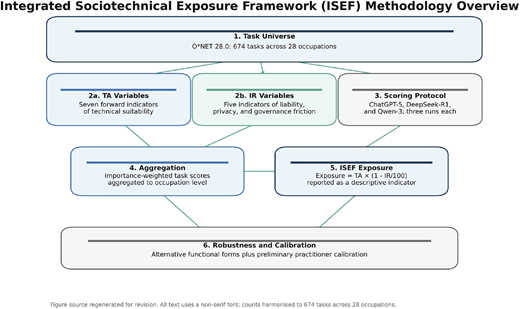
The multiplicative specification is used as the primary model because it represents institutional resistance as a partial gate on technical capability. The overall ISEF procedure is visualised in Figure 1. Exploratory K-means diagnostics are then applied to the standardised occupation-level scores to identify broad patterns within the data; the resulting labels are not treated as validated occupational strata.
Cluster analysis
K-means clustering is applied to standardised occupation-level scores as a diagnostic exercise. Solutions for through are evaluated using the elbow method, silhouette scores, and gap statistics (Tibshirani, Walther, & Hastie, 2001). With only 28 occupations, clustering carries clear risks: small shifts in input weighting can move borderline cases between groups. The main presentation reports the original diagnostic for transparency, but interpretation is deliberately collapsed to broad lower-, middle-, and higher-exposure patterns rather than discrete occupational strata. Supporting diagnostic tables and figures are provided in Supplementary Material C.
One feature of the diagnostic needs a direct word. The singleton diagnostic category contains only one occupation, Engineering Teachers, Postsecondary. The most plausible reading is structural: O*NET task wording for teaching roles is heavy on instruction, curriculum design, and student assessment, which sits awkwardly against the design-and-permit vocabulary that dominates the rest of the sample. The singleton is therefore retained only as a transparent diagnostic artefact. It is not interpreted as a cluster and is not used to support substantive claims. Bootstrap stability is also only moderate in the wider solution; the discussion therefore stays at the level of broad exposure bands and avoids fine-grained cluster identities.
Results
Measurement reliability
Table 3 reports agreement across the three systems. On occupation-level averages, Cronbach's and the ICC both sit around 0.93, which is enough for the descriptive purposes of the paper. Kendall's W tells a less tidy story. Its mean is 0.87, but the range stretches from 0.09 to 0.99, and that spread deserves a serious look before any operational use of the index.
Most occupations sit near the top of the W distribution, where the three systems agree on both the average scores and the within-occupation rank order of tasks. The very low W values are concentrated in a small group of compliance-heavy roles whose task statements lean on words such as “inspect,” “certify,” “ensure,” and “approve.” For these occupations the systems converged on the overall exposure level but disagreed on which sign-off and licensing tasks were the most binding inside the bundle. Two implications follow. First, fine-grained rank ordering is the weakest part of the analysis, and the affected occupations should be flagged for targeted human re-rating before the index is used to inform decisions on individuals or specific workflows. Second, the high mean W cannot be read as independent validation. Where three LLMs trained on overlapping corpora interpret legalistic phrasing in similar ways, the agreement may sit inside the models' shared priors as much as inside the task content. We treat the W extremes as a flag for human review rather than as background noise.
Heterogeneity in exposure (expectation 1)
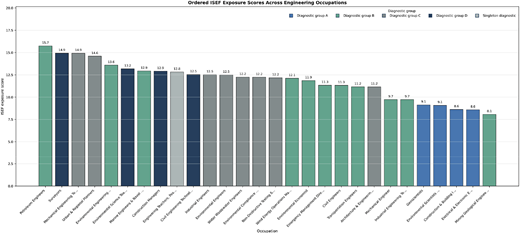
Figure 2 reports ordered ISEF exposure scores for the 28 occupations under the multiplicative specification. Table 4 summarises the exploratory diagnostic groups, and Table 5 reports the occupation-level scores. Scores range from 8.1 to 15.7 on the 0–100 realised exposure index. That observed range is narrow on purpose: once institutional resistance is multiplied in, the safety-critical character of the whole domain compresses exposure even where technical AI suitability is high. Exact ordered scores are retained for transparency and reproducibility, but the analysis does not treat adjacent ranks as substantively distinct.
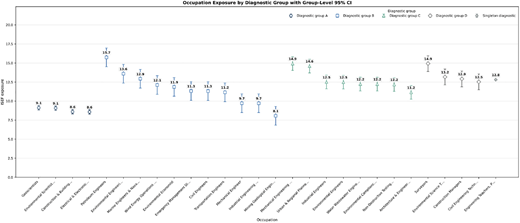
Civil Engineers (11.3) and Transportation Engineers (11.2), for example, sit too close to treat as meaningfully different given the measurement noise documented above. The interpretive weight sits in the TA/IR decomposition and in broad bands: a small group of occupations combine high TA with especially high IR, others sit on lower IR floors, and another set is moderate on both axes. The diagnostic summaries in Table 4 and Figure 3 carry the same caveat—the singleton diagnostic group and only moderate bootstrap stability mean the labels are visual aids, not discrete categories. Most visible variation comes from differences in institutional resistance, with technical capability moving less.
Technical suitability under institutional constraint
Splitting TA and IR brings out a pattern that gets blurred when both are folded into one score. Among occupations with similarly high technical potential, the ones with stronger institutional resistance end up with noticeably lower exposure. The whole sample is regulated work, which keeps the gap muted, but the pattern is still readable in the numbers.
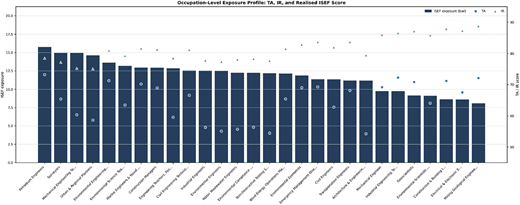
Mining & Geological Engineers and Petroleum Engineers make the point concrete. Both sit above 72 on TA. The Mining role pairs that with very high IR (88.8) and ends up at the bottom of the exposure ladder (8.1); the Petroleum role sits on lower resistance (78.5) and lands at 15.7. The comparison is not meant to suggest that one occupation is “more exposed” in any absolute sense. The point is that two technically similar roles get pulled in opposite directions by their institutional surroundings.
This is the same gap that technical-only exposure indices tend to read over. A task can look well suited to AI assistance and still sit inside a workflow where a licensed engineer's signature is the final binding step.
Divergence from technical indices
To see how the rankings diverge from technical-only measures, the relationships between exposure, TA, and IR are examined across the 28 occupations. Exposure correlates strongly and negatively with institutional resistance (); its correlation with technical potential is small and slightly negative (). These are descriptive diagnostics, not causal estimates, but they point to a clear pattern within this regulated domain: institutional resistance does most of the work in shaping the final exposure scores.
The same pattern helps explain why technical-only indices can mis-rank occupations whenever IR is both high and unevenly distributed. In civil engineering, governance and liability constraints look more consequential for near-term exposure than marginal differences in model capability. Occupation-level TA, IR, and exposure profiles are reported in Figure 4; variable-level model means are reported in Table 6.
Heatmap patterns
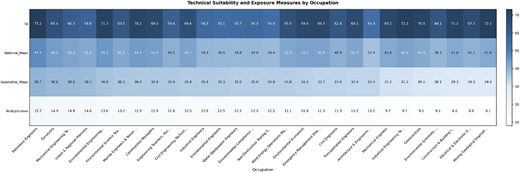
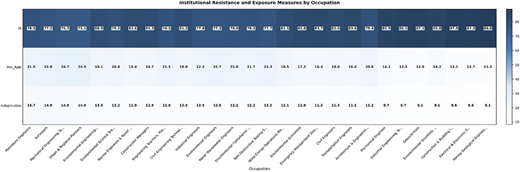
Figures 5 and 6 show technical-side and institutional-side heatmaps across the 28 occupations. The heatmaps use a consistent DTS-style blue-to-deep-blue scale and place occupation names on the bottom axis for readability. Reading the two side by side makes one feature obvious: institutional resistance is rarely spread evenly across a role. In most occupations it concentrates in a small cluster of legally sensitive tasks—permits, signoffs, safety checks, and audit-facing documentation—and those few tasks tend to drive the IR score for the whole occupation.
The comparison also has implications for how exposure is interpreted. Where institutional resistance is concentrated in a limited set of accountability-related tasks, changes in governance arrangements and signing responsibilities may have a greater effect on occupational exposure than incremental improvements in the underlying AI tools. This suggests that exposure cannot be assessed from technical capability alone, particularly for tasks involving formal approval, safety assurance, and regulatory accountability.
Validation checks
Several checks were run on the scoring protocol, the functional form, and the plausibility of the IR rubric. These checks are deliberately separated from validation claims. The practitioner survey helps calibrate the TA/IR split across 15 concrete task vignettes, the FAR-clause mapping illustrates why institutional resistance belongs in the construct, and the benchmarking exercise checks the technical component against prior exposure measures. None of these exercises is treated as a substitute for a same-task expert panel.
Functional Form Justification. The multiplicative specification (Equation 4) treats institutional resistance as a gate, not a marginal offset. In high-stakes engineering work, a licensed engineer's signature requirement can suppress the practical exposure of a design task that otherwise looks highly suitable for AI assistance. Exposure therefore falls towards zero as resistance approaches its upper bound. The logic is theoretical, not statistically identified, which is why alternative specifications are tested below.
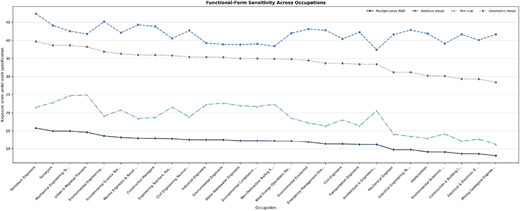
Sensitivity Analysis. Occupational scores were compared across four functional forms: additive mean exposure (), multiplicative exposure (), a min-rule specification (), and an equal-weight geometric mean of technical potential and realised institutional permission. Table 7 and Figure 7 summarise the diagnostics. The additive mean produces a noticeably different fine-grained ordering from the multiplicative model (Spearman ), while the min-rule is more closely aligned but still changes several ranks (Spearman ). The equal-weight geometric mean is rank-equivalent to the multiplicative model (Spearman ), because both are monotonic functions of . These results strengthen the main caution of the paper: broad exposure bands are more defensible than exact occupational ranks. The occupations that move most across specifications include Industrial Engineering Technologists and Technicians, Water Wastewater Engineers, Environmental Engineers, and Non-Destructive Testing Specialists. Weighted and unweighted O*NET aggregation produce nearly identical multiplicative rankings (Spearman ).
Illustrative Anchoring via Contract Clauses. Supplementary Material D maps three representative US federal procurement workflows to the institutional-resistance rubric. Engineering work in these settings is governed by inspection, audit, records, and acceptance clauses such as FAR 52.246-4 (Inspection of Services) and FAR 52.215-2 (Audit and Records). Three contracts cannot validate the index. They are useful for showing why liability, auditability, and review requirements belong inside the IR construct in the first place.
Cross-Index Benchmarking. TA scores were benchmarked against established technical exposure indices (Eloundou et al., 2023; Felten et al., 2021). TA here means technical suitability for generative AI assistance, with no claim of full task automation. The correlation with prior “Exposure” scores is strong (), so the technical side of ISEF tracks existing capability measures closely. Final ISEF exposure diverges from those rankings once IR is applied; the divergence is part of the contribution, since governance acts as a gate on what counts as workable exposure. Table 8 summarises the comparison.
Preliminary Practitioner Calibration. A short practitioner survey was fielded during the revision period as preliminary calibration, not validation, because a fair criticism of the main scoring exercise is that LLMs are being asked to grade work LLMs may one day do. The questionnaire in question.png presented 15 concrete civil, environmental, and adjacent engineering task vignettes, including drilling-plan design, environmental permit preparation, site-plan compliance review, legal boundary descriptions, notices of violation, FEA stress analysis, and building-inspection sign-off. For each vignette, respondents scored two independent 0–10 dimensions. D1 asked how much generative AI could technically assist the task assuming no legal, liability, or sign-off restrictions. D2 asked how much actual sign-off requirements, professional liability, regulatory compliance, and audit traceability limit the use of AI-generated outputs.
The raw Google Forms export contained 11 anonymous records. Two were removed because they did not contain the full set of D1/D2 task ratings and professional-judgement confirmations. The cleaned file therefore retains 9 complete responses across all 15 vignettes. The retained panel includes academic/researcher, mid-level engineer, senior engineer, and government/regulator roles; 6 of the 9 respondents reported holding a PE licence. Table 9 reports the vignette-level means after these exclusions. This preliminary calibration does not validate the 674-task scoring item by item, the occupation-level ISEF index, or the constructed calibration-only adjusted score; no expert–LLM task-level correlation is reported. What it checks is narrower: whether practitioners draw a similar broad distinction between technical usefulness and institutional permissibility when judging realistic engineering tasks.
On that limited question, the pattern is consistent with the framework. Technical assistance is rated highest for course-material development (Engineering Teacher, mean D1 = 8.7), permit application preparation (Environmental Engineer, D1 = 7.2), and radiographic-image interpretation (NDT Specialist, D1 = 7.0). Institutional constraints are rated highest for notices of violation (Environmental Inspector, mean D2 = 8.3), completed building-inspection sign-off (Construction Inspector, D2 = 8.3), facility compliance inspection (Environmental Engineer, D2 = 8.0), and legal boundary descriptions (Surveyor, D2 = 7.7). The constructed calibration-only adjusted score (AI Help ) is highest for course-material development (6.4) and lowest for building-inspection sign-off (0.2) and notices of violation (0.4); it is a descriptive summary of these nine responses, not a validated exposure measure. Across the 15 task means, AI assistance potential and institutional constraints are strongly negatively associated (; ), while AI assistance potential and the calibration-only adjusted score are strongly positively associated (; ). The survey therefore supports the core TA/IR distinction, while still falling short of the larger same-task expert panel needed for full validation.
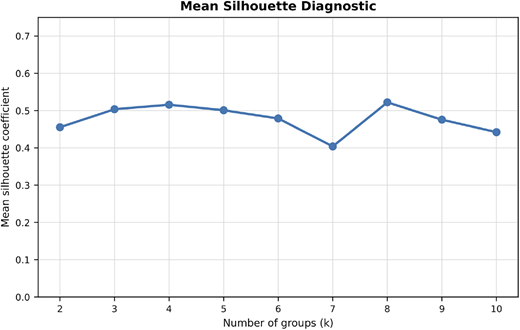
Reliability and Dispersion. Within-system variation averaged 0.73 on a 0–10 scale, and 89% of task-variable pairs showed low dispersion. Even so, a small set of occupations showed weaker cross-model rank agreement, which is why the cluster results are treated as exploratory. The silhouette analysis in Figure 8 supports the use of groupings for description, but not as stable occupational classes.
Discussion
Reading exposure as a sociotechnical indicator
Civil and environmental engineering is governed at least as much by review chains as by technical skill. Licensure, liability, and regulated sign-off decide what counts as acceptable evidence, who is allowed to issue it, and who carries the risk when something goes wrong. ISEF starts from that working reality and keeps it inside the measurement instead of treating it as background.
Several occupations in the sample combine high technical potential with substantial institutional resistance. The resulting exposure scores stay inside a moderate band, so “high exposure” here is a relative position within a regulated profession; it is not a prediction of displacement. The plausible entry points for generative AI in this domain sit at the edges of the workflow—drafting, checking, summarising, and supporting documentation—where outputs can be folded into review routines that already exist.
ISEF does not claim to capture every driver of adoption. Firm strategy, procurement culture, informal professional norms, and individual project leadership all matter and sit largely outside the index. What the framework adds is a way of keeping governance conditions in the same analytical frame as technical suitability, which task-only exposure measures struggle to do.
When technical fit meets accountability limits
The roles that look most open to AI assistance—structured design calculations, simulation support, technical documentation—are also the ones tightly coupled to public safety and infrastructure reliability. The same coupling keeps institutional resistance high in precisely the places where technical scores are high.
There is a forward-looking edge to this observation. As generative models become more capable, the consequences of an undetected error scale with them. If AI-assisted outputs feed into safety-critical work, oversight requirements may tighten before they relax. Institutional resistance can therefore be a durable feature of the profession, not just a temporary lag behind the technology.
The picture is also less uniform than the occupation-level numbers suggest. Project governance, signing authority, and how individual firms allocate work between licensed and unlicensed staff almost certainly matter below the occupation level. Differences across licensure and liability regimes will also pull the same occupation in different directions across jurisdictions.
Potential applicability beyond engineering
ISEF is designed around a general regulated-work principle: technical capability becomes practically relevant only after it passes domain-specific accountability, documentation, privacy, and authority requirements. That principle may be useful in professions such as healthcare, law, accountancy, architecture, and regulated utilities, where AI-assisted outputs may be technically plausible but cannot be adopted without professional oversight. Transfer is not automatic. Each domain would need its own task universe, regulatory map, IR indicators, weights, and practitioner calibration; for example, clinical governance and patient confidentiality are not interchangeable with engineering sign-off and infrastructure liability. ISEF should therefore be treated as a portable measurement architecture rather than a ready-made cross-profession score.
Updating ISEF as capabilities and regulation change
Both sides of the framework are time dependent. Technical suitability can change as models gain tool use, multimodal reasoning, reliability controls, or domain-specific evaluation evidence. Institutional resistance can also change as regulators issue guidance, insurers revise coverage, clients amend procurement requirements, and professional bodies clarify acceptable review and sign-off practices. A future longitudinal implementation should version the TA and IR rubrics, retain dated regulatory evidence, re-score a fixed task panel at planned intervals, and reconvene a larger practitioner panel when material changes occur. Such updates would allow observed changes in exposure to be separated from changes in the measurement rule itself.
What this means in practice
For workforce planning, exposure is most defensible as a descriptive baseline; it should not be read as a direct estimate of job-loss risk. In regulated roles, AI use is likely to settle first on documentation and analytical support, where outputs can be slotted into audit trails and existing oversight routines.
For governance, the framework surfaces a tension between AI capability and existing liability arrangements that will not dissolve quickly. The concrete levers sit exactly where that tension lives: AI-specific clauses in engineering procurement contracts, professional indemnity guidance for AI-assisted deliverables, audit-trail requirements for generated outputs, and clearer rules on whether a professional engineer's sign-off can rely on AI-supported calculations or documentation. These are not marginal adjustments to an exposure score; they decide which parts of a workflow are institutionally permissible in the first place.
For training and professional development, the heterogeneous exposure profiles imply differentiated needs. Some roles benefit from stronger emphasis on integrating and supervising generative tools; others need more weight on competencies tied to accountability, public safety, and document defensibility.
Limitations
A few limitations deserve to be named openly rather than left to the framing. LLM scoring showed strong agreement across the three systems, and that agreement may partly reflect shared training priors, especially in how legalistic phrasing is read. The practitioner survey adds an external check, but it is not the same as asking engineers to re-score the same O*NET tasks. Nine complete respondents provide preliminary calibration only; they cannot support population-level claims, task-level validation, or validation of the constructed calibration-only adjusted score. A larger, purposively stratified expert panel should re-score the same O*NET tasks sampled from high-, medium-, and low-exposure occupations, report inter-rater agreement and uncertainty, and test whether calibration patterns replicate across professional roles and jurisdictions. This design would allow direct expert–LLM correlations to be estimated.
Institutional resistance is also, openly, a constructed measure. Different rubric items, weightings, or functional forms would shift the resulting exposure profile. The current reading is a cross-section of present-day conditions; it does not track how procurement standards, professional indemnity, or sectoral regulation may move under generative AI. Following exposure through time, and linking it to observed adoption inside real projects, is work for the next study.
Conclusion
ISEF was built to look at generative AI exposure in civil and environmental engineering through two lenses at once: what a task is technically suited to, and what institutional rules will let through. The aim is descriptive. The framework reports where suitability and governance constraints meet; it does not try to time adoption or forecast job loss.
Applied to 674 tasks across 28 occupations, the analysis surfaces a pattern that is easy to miss when only the technical side is measured. Many roles read as open to AI assistance, yet the exposure score stays inside a moderate band once liability, compliance, and sign-off requirements are added to the picture. Indices that leave the institutional side outside the measurement will tend to misread how generative AI is likely to enter regulated engineering work in the near term.
The more useful question that follows is set at the workflow level, not the occupation level. Which parts of a typical project become institutionally permissible for AI support, under what review arrangements, and with what liability conditions? The same question can be tested in other regulated professions only after their institutional conditions have been specified and calibrated. The released data, scoring rubric, and code are intended as a starting point for that kind of follow-up: larger same-task expert panels, adoption-linked case studies, longitudinal rubric updates, and project-level tracing of where review and responsibility actually shift.
Ethics statement:
The main analysis uses publicly available occupational task data. The revision also reports an anonymous practitioner calibration survey that collected professional judgements without personal identifiers or sensitive personal data. Ethical approval was not required under the author's institutional understanding for this minimal-risk anonymous consultation.
I sincerely thank my supervisor, Dr Stephen Suryasentana, for his guidance and support throughout the research. I am also grateful to all participants who contributed to the calibration. Finally, I thank the reviewers for their detailed and constructive feedback across several rounds of view.
The supplementary material for this article can be found online: